Stop Revenue Gaps: 4 Step Server Side Tracking for Marketers and IT
Server-side tracking routes events to a server you control before forwarding them to analytics and ad platforms. It’s a first-party collection endpoint that parses, filters, and enriches data before it ever reaches Google, Meta, or another vendor. The payoff is reliable delivery, real privacy controls, and faster pages, but most teams don’t need to go all-in. A hybrid setup, where critical events move server-side and everything else stays client-side, is the right call for the vast majority of businesses.
TL;DR:
- Server-side tracking improves event recovery by bypassing browser ad blockers and restrictions, potentially recovering a significant share of lost signals.
- It enhances data control, allowing custom redaction and hashing of sensitive information before forwarding, and offers more reliable delivery of revenue-critical events like purchases.
- Implementation options include self-hosted containers, managed hosting, or edge workers, with costs influenced heavily by engineering hours and maintenance needs.
- Moving to server-side does not exempt users from legal consent requirements; compliance efforts must be centralized and enforced at the server level.
- A hybrid approach, starting with high-value events and expanding gradually, delivers the best ROI without the risks of full migration.
Table of Contents
- How Server-Side Tracking Works: Architecture and Common Patterns
- What Server-Side Tracking Improves in Practice
- Client-Side vs Server-Side Tracking: What Each One Captures
- When Should You Actually Adopt Server-Side Tracking?
- Implementation Options and What They Actually Cost
- Does Server-Side Tracking Change Your Privacy Obligations?
- How Do You Keep Server-Side Tracking Trustworthy After Launch?
- How Tatemweb Approaches Server-Side Tracking Projects
- Why the Hybrid Approach Wins for Most Teams
- Get Help Implementing Server-Side Tracking the Right Way
- Sources
- FAQ
How Server-Side Tracking Works: Architecture and Common Patterns
Picture a thin layer on your website that does almost nothing except capture what happens and post it somewhere safe. That’s the client side of a server-side setup. Instead of a browser script firing directly to a dozen ad platforms, it sends one clean payload to a collection endpoint you own, typically a subdomain of your own domain, connected through a CNAME record.
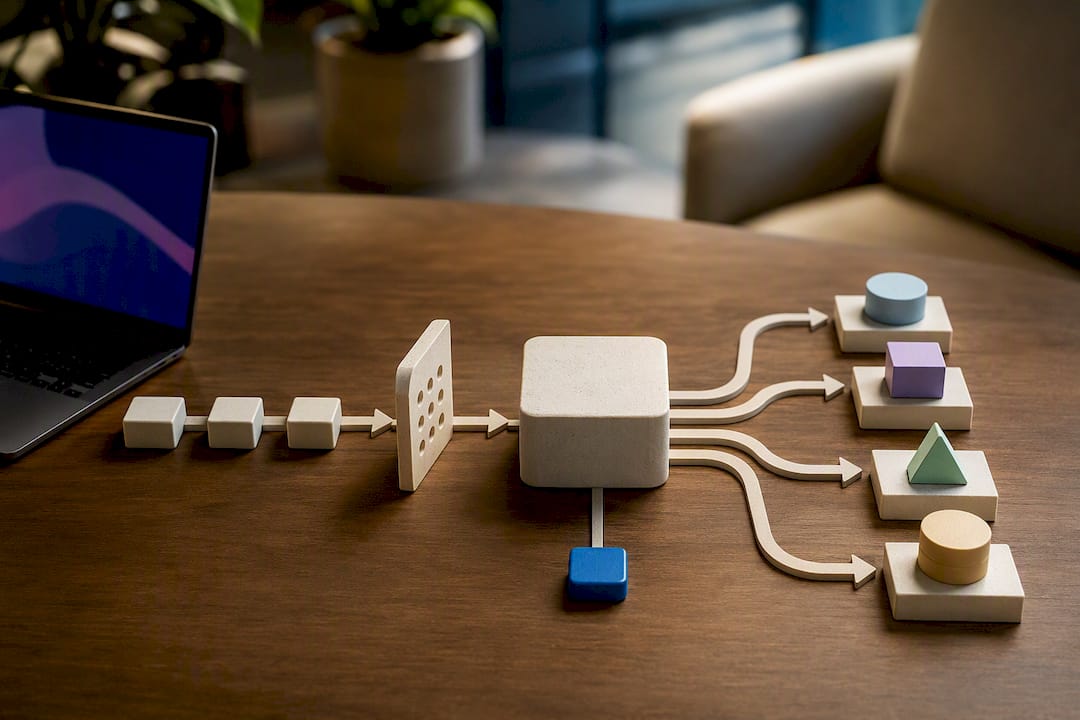
From there, a server container takes over. It parses the incoming event, applies your consent rules, strips or hashes anything sensitive, and forwards a cleaned-up version to each destination through server-to-server APIs. Google documents this pattern directly for Google Tag Manager server containers, which run in a cloud environment you configure, most often Cloud Run or App Engine.
You’ve got three realistic hosting paths:
- Self-hosted GTM server on Cloud Run or App Engine, giving you full control but real operational overhead.
- Managed hosts that run the container for you, trading some control for lower maintenance.
- Edge workers, like Cloudflare Workers, which run closer to the visitor and cut latency but require actual code to maintain.
Domain and TLS setup aren’t paperwork here, they’re the whole point. A properly configured first-party subdomain with valid SSL is what keeps your server-set cookies behaving like first-party cookies instead of getting flagged by browser privacy rules.
What Server-Side Tracking Improves in Practice
The biggest draw is signal recovery. Ad blockers and browser restrictions strip out a real chunk of client-side tracking calls before they ever fire, and server-side routing sidesteps a lot of that filtering because the request never looks like a third-party tracking script to begin with.
Practitioner reports put realistic recovery in a range from about a low to a moderate share of lost events, depending on your audience’s blocker usage and browser mix, according to analytics implementation research. That’s a wide range on purpose. A site full of privacy-conscious tech workers running uBlock Origin recovers more than a site full of casual mobile visitors who’ve never touched an ad blocker.
Beyond recovery, the practical wins stack up fast:
- Fewer third-party scripts loading in the browser, which helps Core Web Vitals scores and page speed.
- Direct control over redaction and hashing before data leaves your server, rather than trusting a dozen vendor scripts to behave.
- Custom mapping rules per destination, so different vendors get different levels of detail.
- More reliable delivery for revenue-critical events like completed orders, subscription renewals, and payment confirmations.
That last point matters more than it sounds. Losing a random button click to an ad blocker is a rounding error. Losing purchase confirmations means your reported revenue and your actual revenue stop matching, and that erodes trust in your entire measurement stack.
Client-Side vs Server-Side Tracking: What Each One Captures
Neither layer replaces the other, they cover different ground. Client-side tracking lives in the browser and sees things a server never will on its own: UTM parameters, user agent strings, scroll depth, DOM interactions, and session behavior. It’s also the easier of the two to set up, since most analytics platforms are built around a JavaScript snippet you drop into a page.
Server-side tracking shines with backend data your browser script never touches directly, like order status changes, subscription events, or CRM updates, and it lets you enforce consent and redaction rules in one controlled place rather than across dozens of scattered scripts. The most pragmatic teams pass browser context forward rather than picking one layer exclusively, using a thin client-side post to carry UTM data, user agent, and session ID into the server pipeline.
| Signal type | Best captured by |
|---|---|
| UTM parameters, referrer data | Client-side |
| DOM interactions, scroll depth | Client-side |
| Order and payment confirmations | Server-side |
| Subscription and CRM events | Server-side |
| Consent enforcement, PII redaction | Server-side |
| User agent, session context | Client-side (passed to server) |
When Should You Actually Adopt Server-Side Tracking?
Not every business needs a server container. The teams that see real ROI usually share a few traits: meaningful paid ad spend where conversion accuracy directly affects budget decisions, recurring revenue tied to accurate attribution, or handling of regulated data where centralized consent enforcement matters.
Long sales cycles amplify the case too, since a lead that converts 60 days after a blocked ad click needs a tracking layer that doesn’t rely on a cookie surviving that long in Safari.
A minimal, low-risk rollout looks like this:
- Audit your current tracking to find which events are already unreliable or missing, especially purchases and signups.
- Move the highest-value events server-side first, not everything at once, starting with revenue and conversion confirmations.
- Run both systems in parallel for two to four weeks, comparing server-reported numbers against your order system or CRM.
- Expand gradually to additional events once match rates hold steady and nothing is silently dropping.
Pro Tip: Don’t migrate your entire tag setup in one weekend. Move purchases and signups first, watch the reconciliation numbers for a few weeks, and let the data tell you whether expanding further is worth the engineering time.
Implementation Options and What They Actually Cost
Budget is where most server-side projects go sideways, usually because teams price the hosting bill and forget the engineering hours. A self-hosted GTM server container on Cloud Run gives you the most control, but it comes with real setup and maintenance work: someone has to configure DNS, manage SSL certificates, and watch container health.
Rough cost ranges reported by practitioners run from modest to moderate amounts per month for self-hosted Cloud Run setups and managed hosting tiers depending on event volume. Either way, expect 40 to 80 hours of engineering time for the initial build, not the hosting fee, to be your real cost driver.
Your options break down into three categories:
- Self-hosted GTM server: full control, but you own DNS, SSL renewal, uptime monitoring, and container updates.
- Managed hosting: predictable tiered pricing, less setup burden, but you’re trusting someone else’s infrastructure choices.
- Edge workers: cheapest to run at scale but require real code maintenance and typically handle page-view events better than complex interaction tracking.
Watch for two recurring pitfalls. First, Safari’s cloaking rules can cap the lifetime of server-set cookies if your endpoint doesn’t resolve cleanly as first-party infrastructure, a nuance WebKit documents directly. Second, a misconfigured CNAME record is the single most common reason a server-side rollout silently fails validation in week one.
Does Server-Side Tracking Change Your Privacy Obligations?
No, and this is the misconception that trips up the most teams. Moving data collection to a server you control doesn’t loosen consent requirements, it just gives you one place to enforce them consistently. Your consent management platform’s signals still need to reach the server layer and get honored there before anything forwards downstream, a point compliance-focused guides on server-side GDPR handling stress repeatedly.
Build these into the server layer from day one:
- Redact or hash personally identifiable information before it leaves your infrastructure, not after.
- Enforce CMP consent signals server-side, don’t assume the browser already filtered non-consented traffic.
- Log access to raw event data and set retention limits rather than storing everything indefinitely.
- Loop in legal or compliance counsel early if you’re operating under HIPAA, CCPA, or CPRA obligations.
Centralized processing only improves privacy when it’s paired with actual governance and periodic audits, not just a server sitting between the browser and the vendor.
How Do You Keep Server-Side Tracking Trustworthy After Launch?
A server container that silently drops 20% of events is worse than no server container, because you won’t know until your revenue numbers stop reconciling.
- Validate event schema on every deploy so a malformed payload doesn’t quietly break downstream forwarding.
- Monitor delivery status and container uptime, with alerts for failed forwards or unexpected latency spikes.
- Reconcile server-reported purchases against your actual order system weekly, not quarterly.
- Track match rates for tools like Conversions API or Enhanced Conversions as an ongoing KPI, not a one-time launch check.
Operational checklists from tracking-focused practitioners consistently point to reconciliation testing as the step teams skip, and the one that catches problems earliest.
Pro Tip: Set up a simple weekly reconciliation report comparing server-side purchase counts to your order platform’s totals. A gap wider than a few percentage points almost always traces back to a consent-blocking rule or a container misconfiguration, not a mysterious tracking issue.
How Tatemweb Approaches Server-Side Tracking Projects
Server-side tracking sits at the intersection of two things Tatemweb has spent over 26 years building: technical implementation and compliance consulting. When a Florida business asks about moving to a server container, the work usually starts with an audit of what’s already breaking, followed by a scoped implementation plan that accounts for consent enforcement and PII redaction from the outset, not as an afterthought.
For businesses already thinking about broader GA4 measurement setups or exploring cookieless analytics approaches, server-side tracking fits naturally into that same conversation. Deliverables typically include a configured container, documented consent rules, and a monitoring plan so the setup doesn’t degrade silently six months later.
Why the Hybrid Approach Wins for Most Teams
Full server-side migrations sound impressive in a pitch deck, but the businesses that actually benefit are the ones who moved slowly. Start with purchases and signups, measure the recovery against the engineering hours it cost, and only expand once the numbers justify it. Governance matters more than architecture here: someone specific needs to own the container, watch the reconciliation reports, and update consent rules when regulations shift. If nobody internal has the bandwidth for that ownership role, that’s the moment to bring in outside engineering help rather than let the container quietly rot.
— Matt
Get Help Implementing Server-Side Tracking the Right Way
An experienced team is a practical alternative to hiring a full-time engineer just to keep a tracking container running. Instead of guessing at DNS configuration or debugging Safari cloaking issues alone, you get expert support for compliance-sensitive implementations, including HIPAA and PII consulting.
An engagement typically starts with an audit of your current tracking gaps, followed by implementation of the priority events, a compliance review of your consent enforcement, and ongoing monthly monitoring so match rates and container uptime don’t quietly slip. If your team already collaborates with outside agencies on client work, Tatemweb’s approach pairs well with AI-driven agency workflows for scaling that kind of technical project without adding headcount.
Ready to see where your current tracking is losing data? Visit Tatemweb’s AI services page or call 772-224-8118 to schedule an audit.
Sources
- An introduction to server-side tagging
- Intelligent Tracking Prevention (WebKit blog)
- Server-Side vs Client-Side Tracking: 2026 Decision Guide
- When to track on the client vs server (Twilio/Segment resource)
FAQ
What Is Server-Side Tracking?
It’s a setup where events are sent first to a server you control, which then forwards cleaned and consent-checked data to analytics and ad platforms, instead of the browser sending data directly to each vendor.
What Is the Server-Side Tracking Process?
A thin client-side script posts event data to your collection endpoint, a server container parses and enriches that data, applies consent and redaction rules, then forwards it via server-to-server APIs to destinations like GA4.
Is Server-Side Tracking Legal?
Yes, but it doesn’t change your legal obligations. You still have to honor consent management platform signals and follow data protection rules like GDPR or CCPA; server-side just gives you one centralized place to enforce those rules.
What Is the Difference Between Client-Side and Server-Side Tracking?
Client-side tracking runs in the browser and captures things like UTM parameters and DOM interactions easily, while server-side tracking handles backend data like orders and subscriptions with stronger reliability and consent enforcement, and most teams combine both.
Recommended
Tatem Web Design
26+ YearsWeb Design & SEO Specialist · Tatem Web Design
Matt Tatem has been designing websites professionally since 1999, making Tatem Web Design one of Florida's longest-running web agencies. Based in Stuart, FL, he specializes in WordPress, local SEO, Shopify e-commerce, and cybersecurity consulting for small businesses.

Rank in ChatGPT in 90 Days With a Practitioner Led Checklist
Follow a practitioner led 90 day plan to get cited by ChatGPT: allow OAI-SearchBot, publish short answer capsules with schema, and track Bing AI Performance.

AI SEO Content Playbook: 16 GEO Signals for Agencies & Teams
A practical playbook mapping the GEO-16 signals to hands-on editorial workflows, review controls, and metrics. For agencies and in-house teams scaling AI...

Copy Ready Local Schema Markup for SMBs + Google Validation
Copy ready JSON-LD examples and Google validation steps for SMBs' local schema markup. Audit, implement, and verify each location page with confidence.